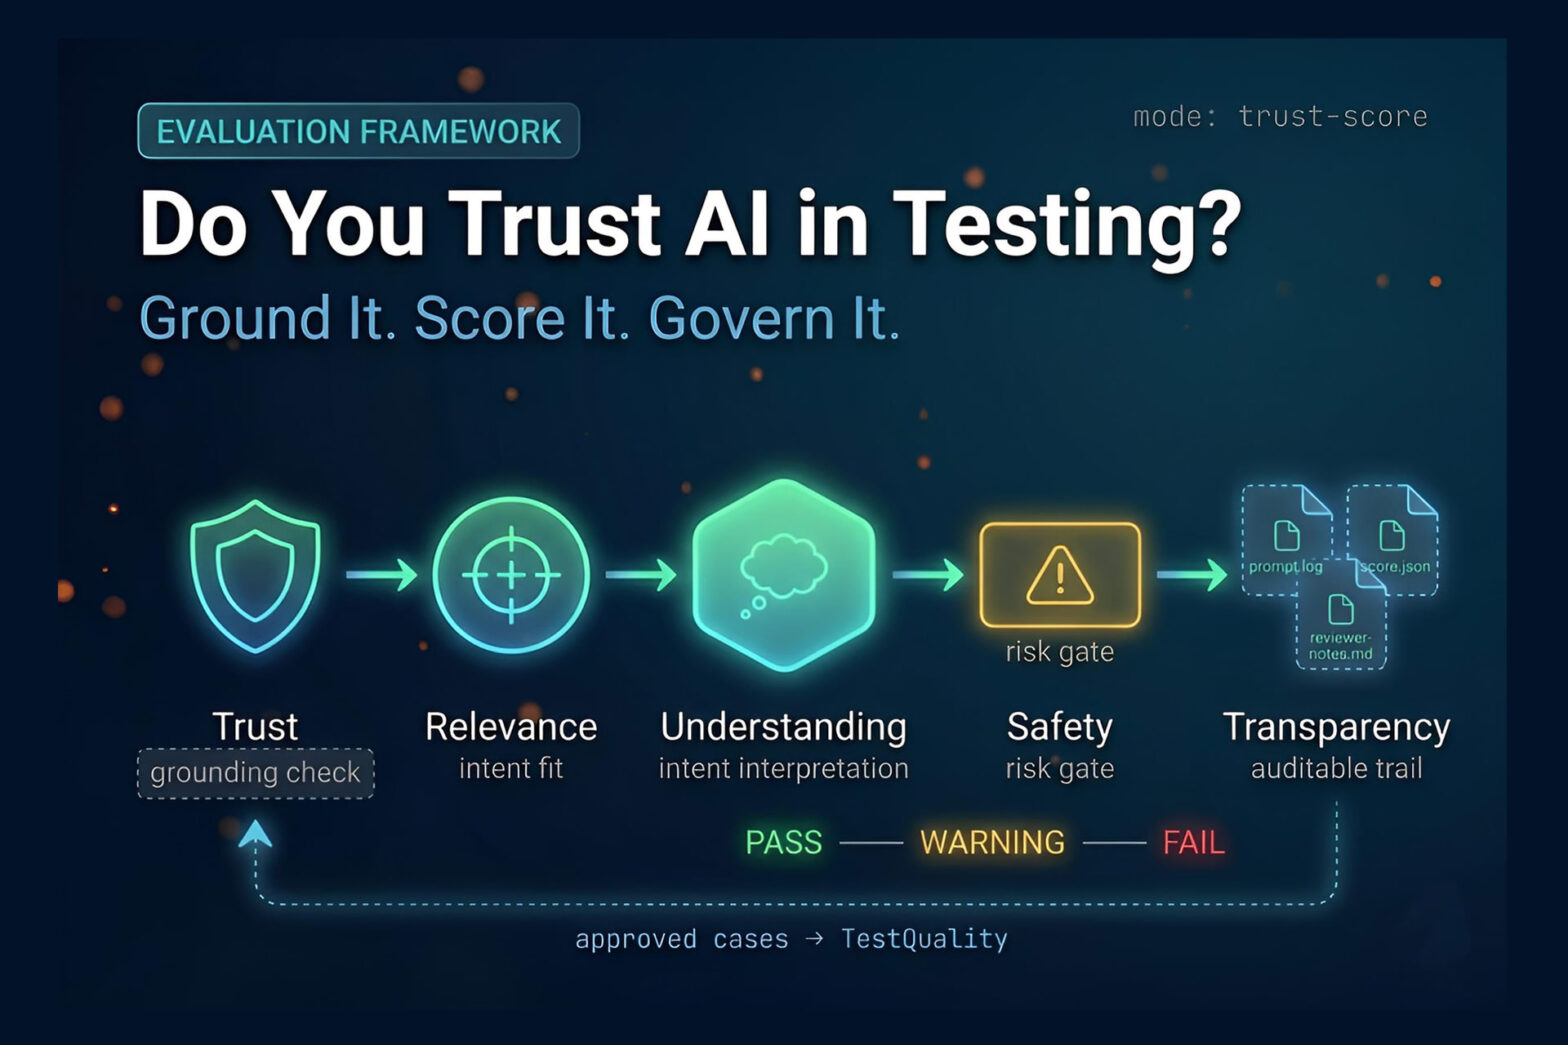
AI trust in testing is the problem of deciding whether an AI system’s output is reliable enough to support release decisions, test creation, coverage analysis, or production workflows. For QA teams, the core issue is that large language model output is nondeterministic, persuasive, and only partially grounded in source evidence — meaning a simple pass… Continue reading Do You Trust AI in Testing? A Framework QA Teams Can Actually Use
Tag: Hallucination Detection
Continuous Evaluation: How to Build an LLM Regression Testing Pipeline in 2026
This is the second article in a three-part Agentic QA series. The first article — Agentic QA Architecture: Reasoning Loops, Self-Healing DOM & Autonomous Testing — covered how AI agents use Plan-Act-Verify loops to autonomously generate and execute test scripts. This article focuses on the prerequisite layer: evaluating and certifying the reliability of the LLM… Continue reading Continuous Evaluation: How to Build an LLM Regression Testing Pipeline in 2026