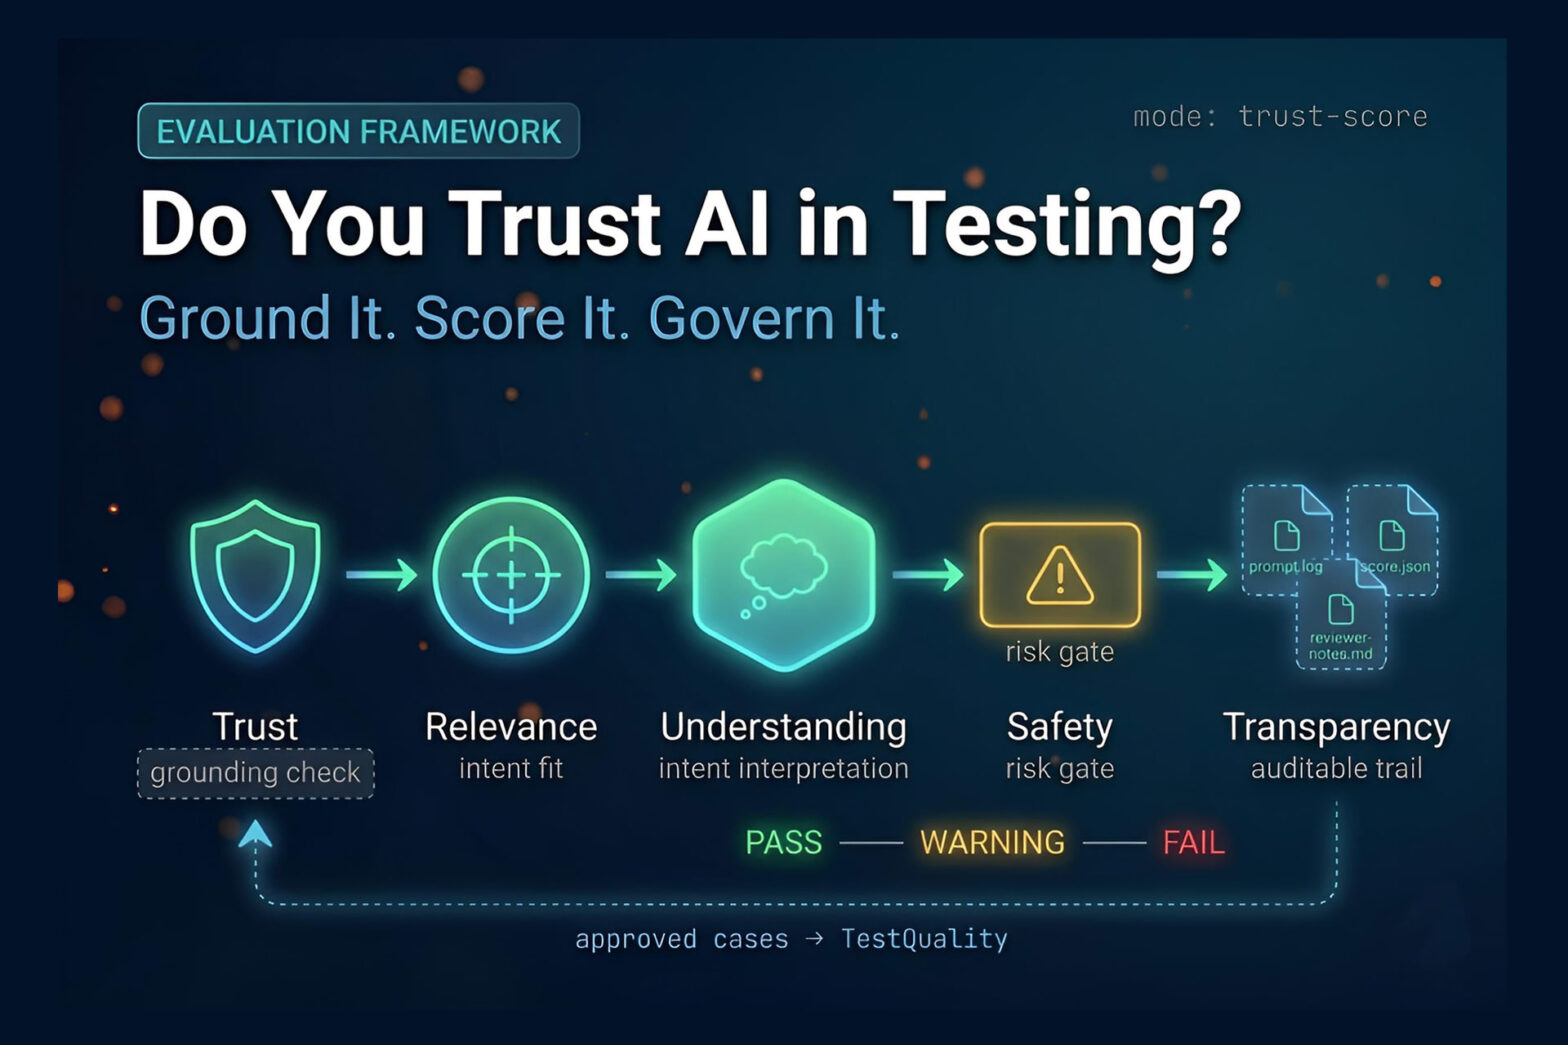
AI trust in testing is the problem of deciding whether an AI system’s output is reliable enough to support release decisions, test creation, coverage analysis, or production workflows. For QA teams, the core issue is that large language model output is nondeterministic, persuasive, and only partially grounded in source evidence — meaning a simple pass… Continue reading Do You Trust AI in Testing? A Framework QA Teams Can Actually Use
Tag: LLM Testing
Playwright Test Agents & MCP: A 2026 Architecture Guide
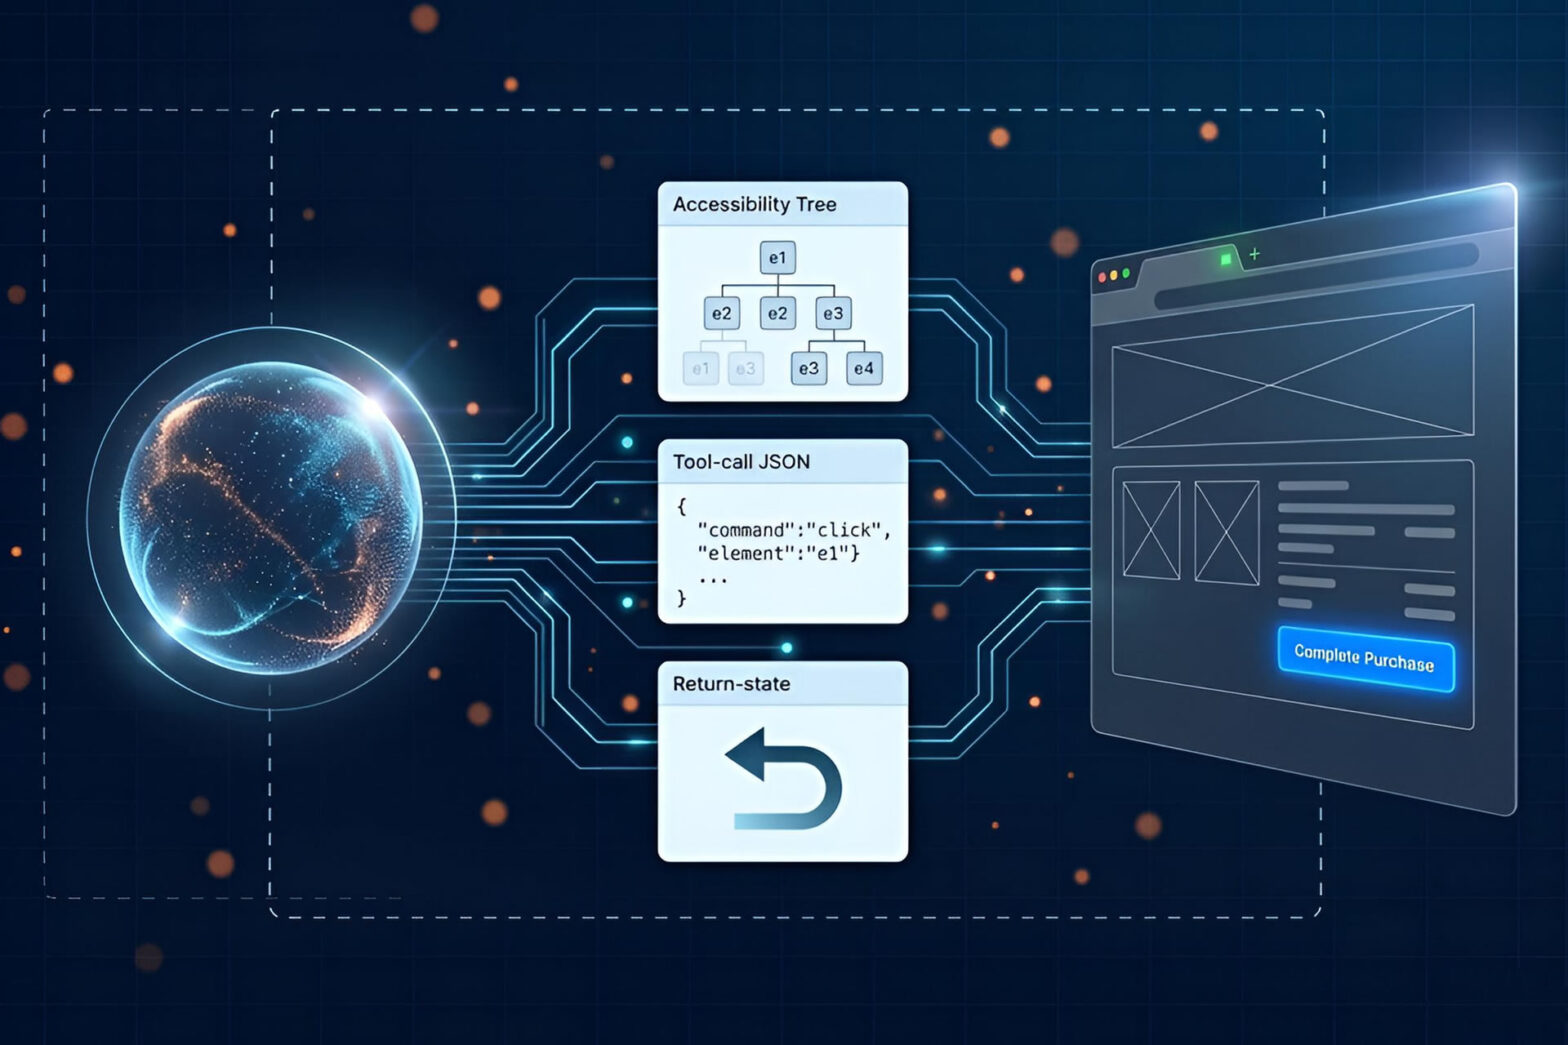
At a Glance Playwright Test Agents and MCP — A 2026 Architecture Decision Strategic guidance for engineering leaders evaluating agentic Playwright workflows Definition: Playwright test agents are LLM-driven execution loops that interpret high-level intent via the Model Context Protocol (MCP), rather than executing hardcoded selectors. Token economics: Microsoft’s MCP server consumes ~200–400 tokens per accessibility-tree… Continue reading Playwright Test Agents & MCP: A 2026 Architecture Guide
Beyond the Basics: Advanced LLM Evaluation Metrics and Strategies for QA Success
The integration of Large Language Models (LLMs) into applications is rapidly transforming the software landscape. As we discussed in our Guide to LLM Testing and Evaluation previous post, while LLMs offer unprecedented capabilities, their non-deterministic nature presents unique and evolving challenges for quality assurance. As QA professionals and developers, we’ve moved past the initial awe… Continue reading Beyond the Basics: Advanced LLM Evaluation Metrics and Strategies for QA Success
A Guide to LLM Testing and Evaluation for Modern QA Teams
Introduction The world of software is undergoing a seismic shift. Large Language Models (LLMs) are no longer a novelty; they are being integrated into a vast array of applications, from customer support chatbots to sophisticated code generation tools. For QA professionals and developers, this represents a new frontier in software testing as well, one that… Continue reading A Guide to LLM Testing and Evaluation for Modern QA Teams