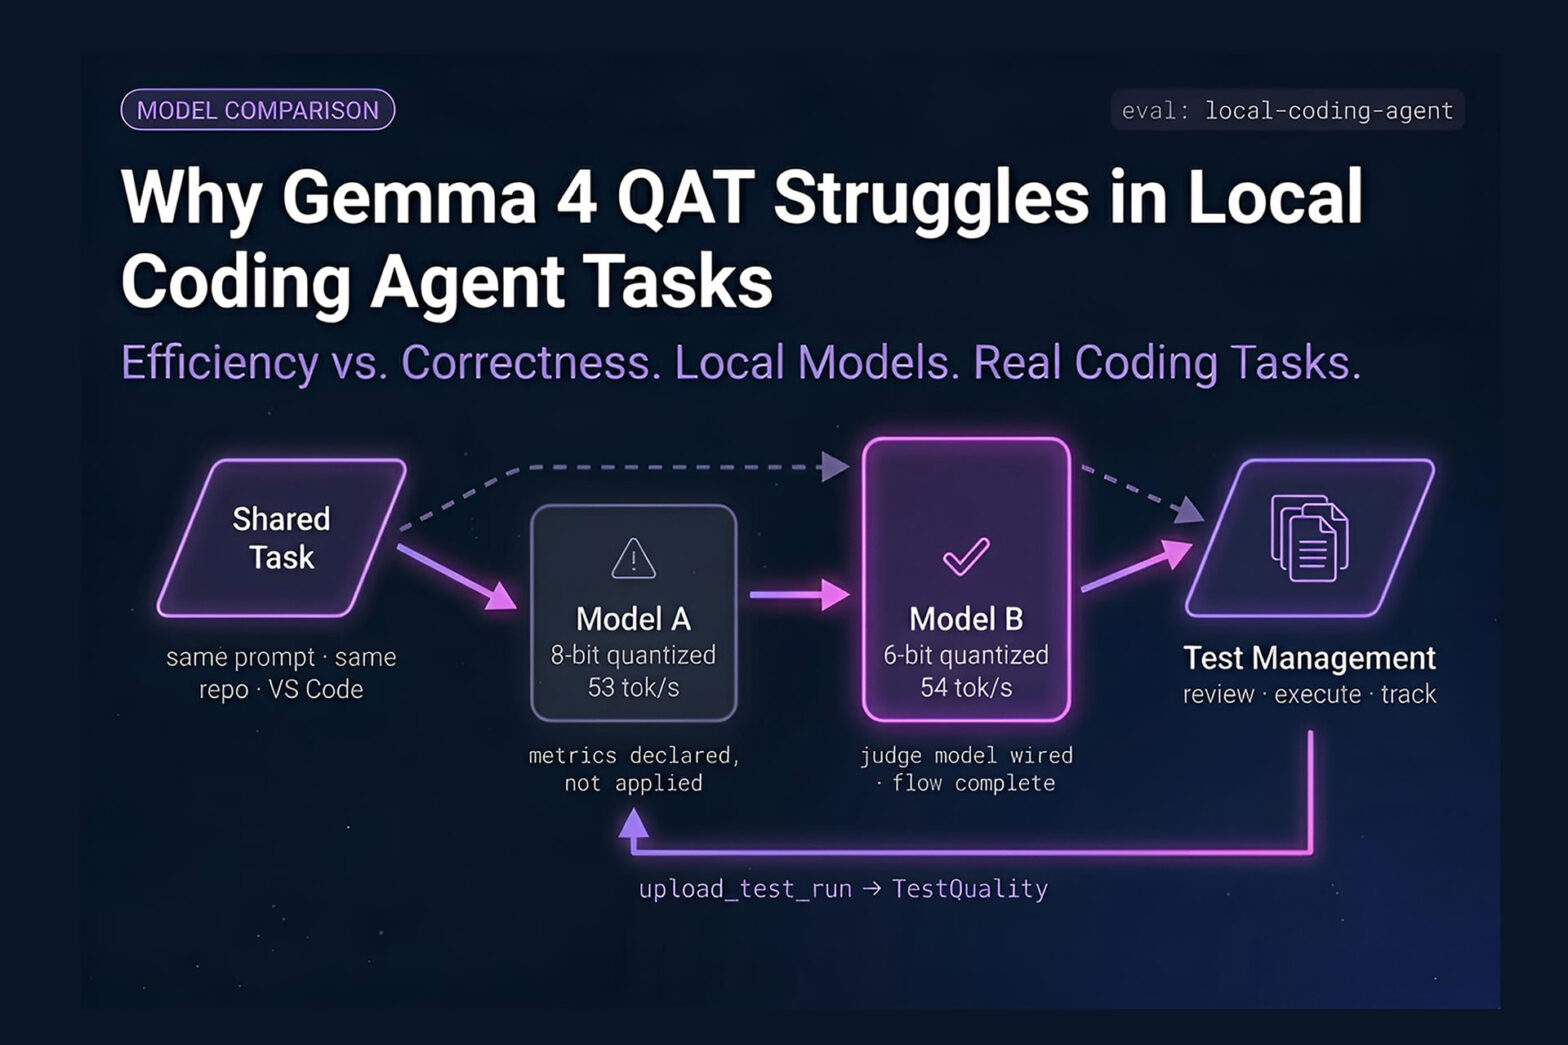
Gemma 4 QAT refers to Google’s quantization-aware versions of Gemma 4, designed to reduce memory use and improve local inference speed on developer machines. In a direct head-to-head coding-agent task using VS Code and DeepEval, Gemma 4 QAT produced structurally incomplete test code — initializing evaluation metrics without applying them correctly and omitting the required… Continue reading Why Gemma 4 QAT Struggles in Local Coding Agent Tasks
Tag: Ai-Assisted Testing
Do You Trust AI in Testing? A Framework QA Teams Can Actually Use
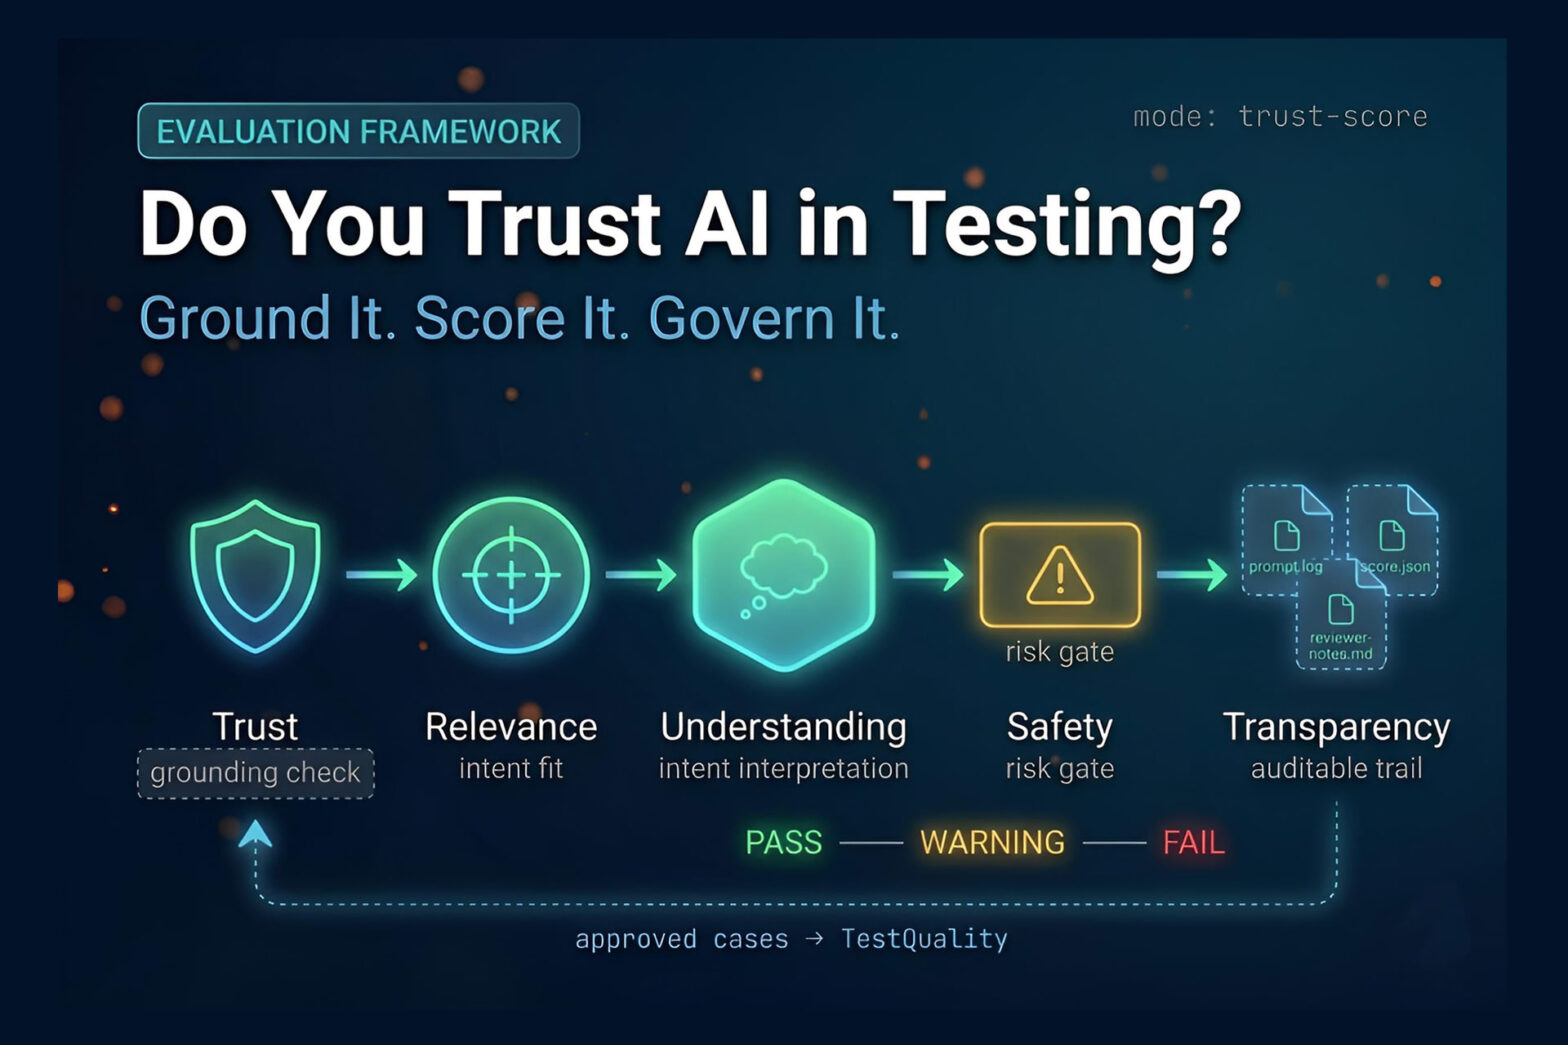
AI trust in testing is the problem of deciding whether an AI system’s output is reliable enough to support release decisions, test creation, coverage analysis, or production workflows. For QA teams, the core issue is that large language model output is nondeterministic, persuasive, and only partially grounded in source evidence — meaning a simple pass… Continue reading Do You Trust AI in Testing? A Framework QA Teams Can Actually Use
Agentic Testing and How QA Teams Can Use Claude Code and Terminal Agents
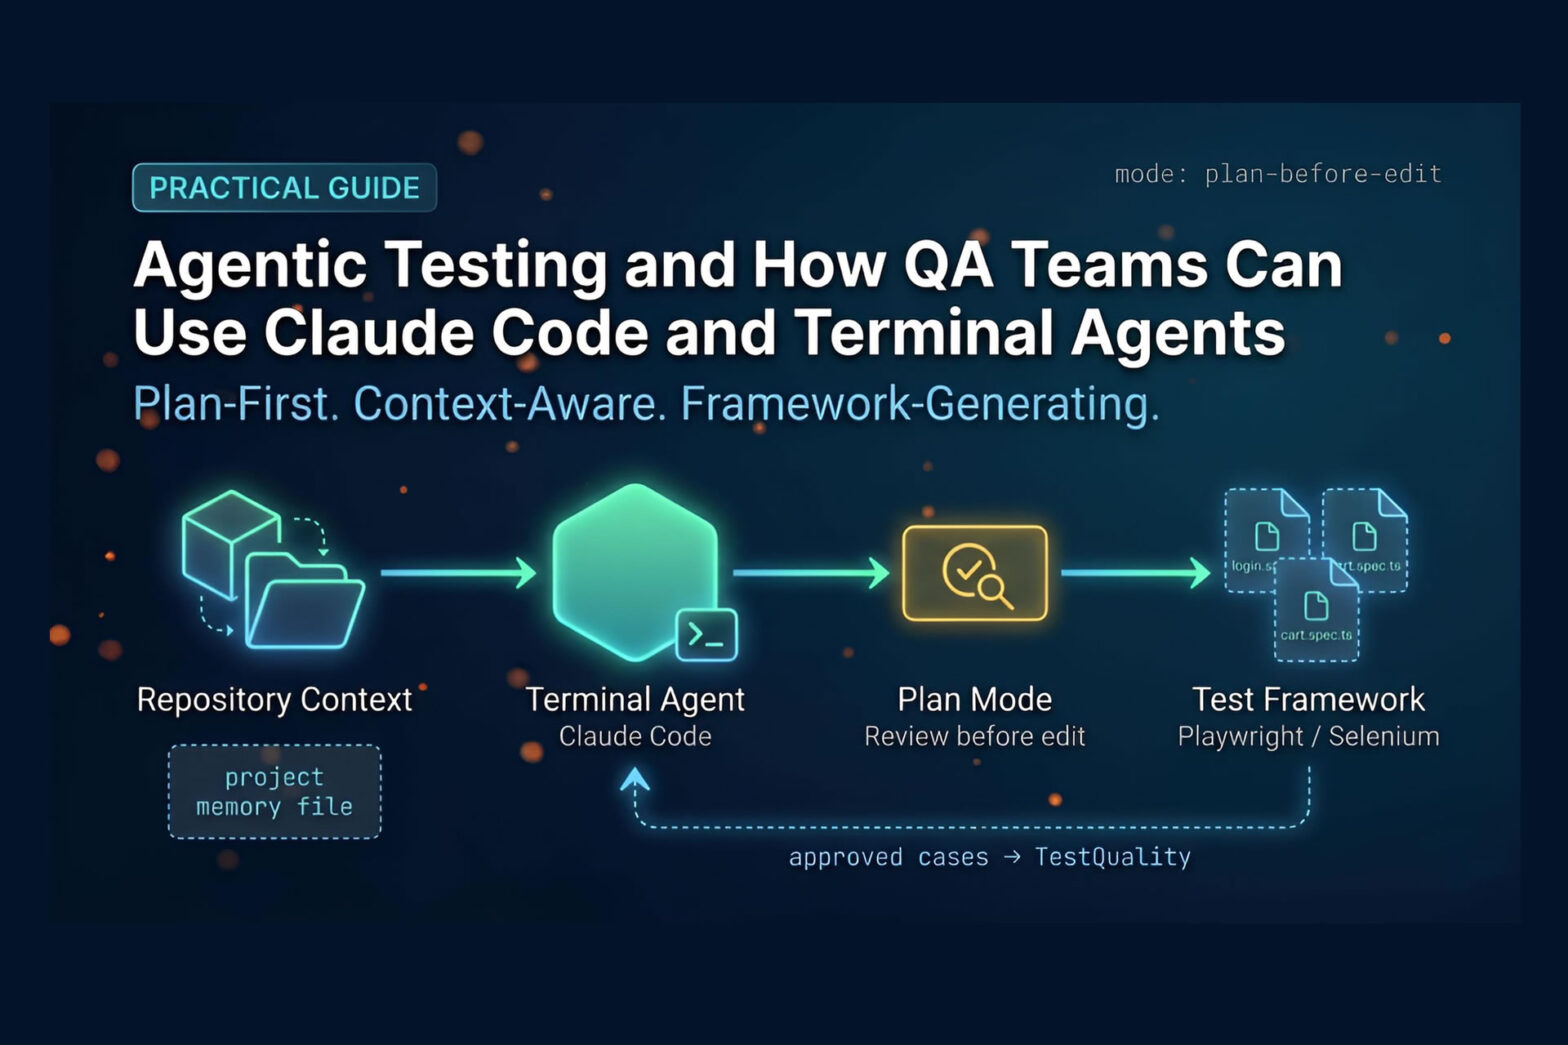
Agentic Testing and QA is a practice in which AI agents operate directly on a project — reading files, planning tasks, generating framework code, and interacting with a browser — rather than simply answering prompts inside a chat window. Tools like Claude Code bring this capability to the terminal, giving QA teams a command-line assistant… Continue reading Agentic Testing and How QA Teams Can Use Claude Code and Terminal Agents
Free and Paid Ways to Run Cloud Code for Agentic Testing and QA
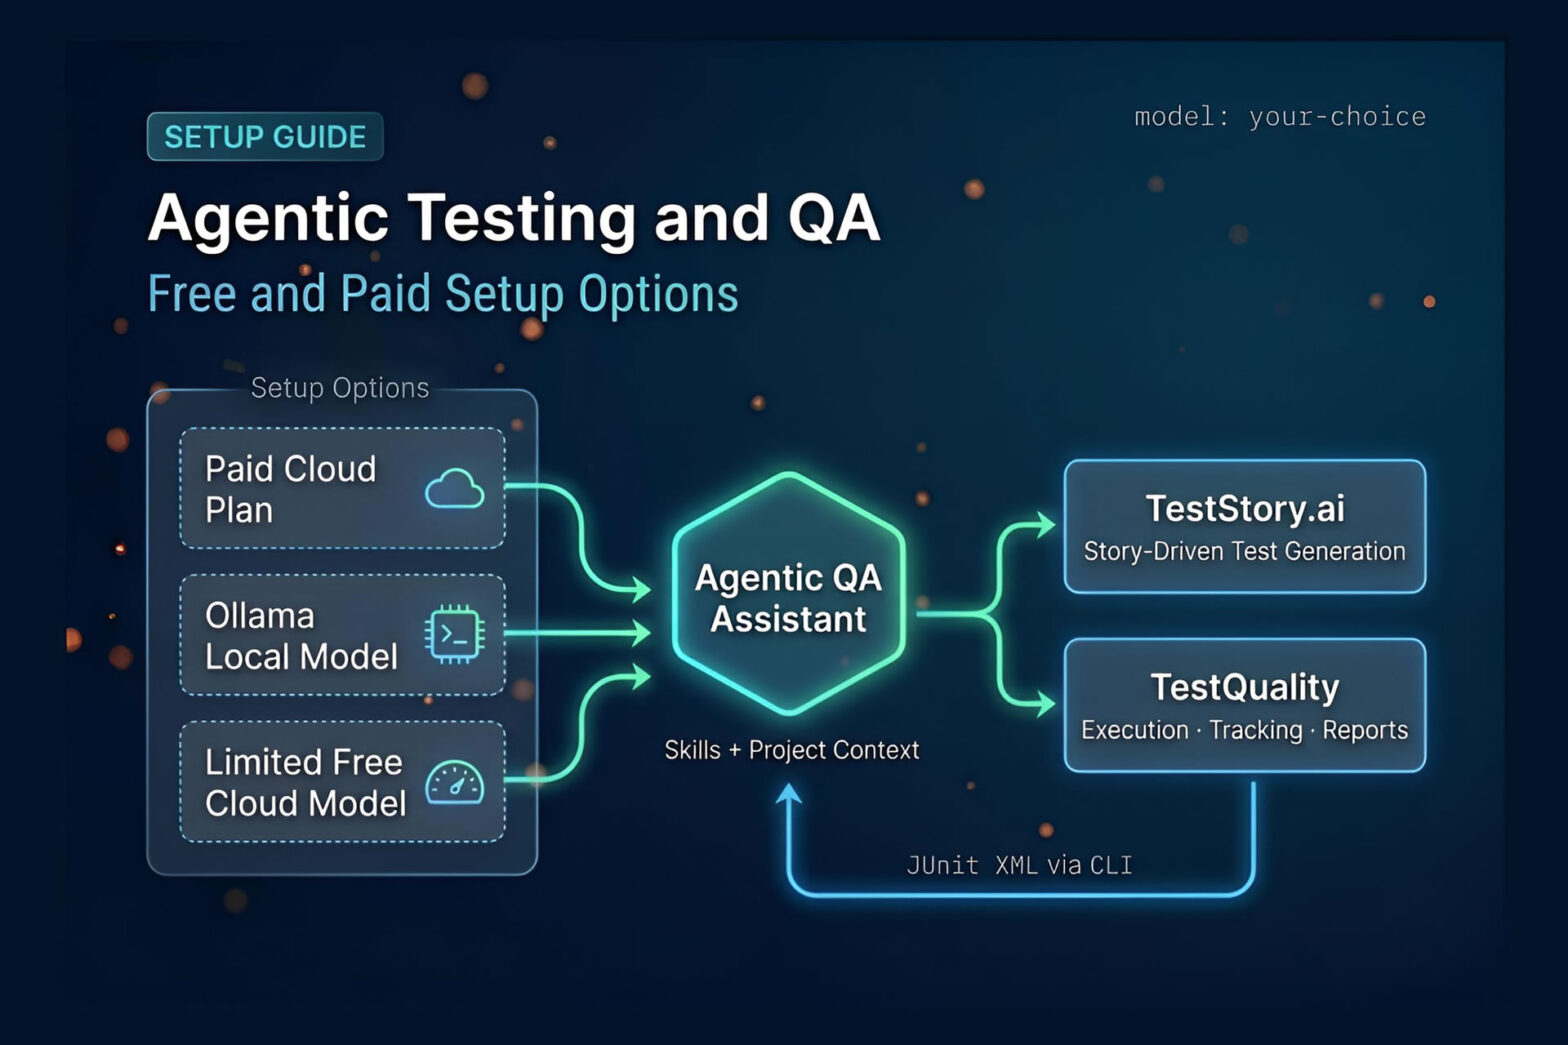
Agentic Testing and QA describes a testing workflow where an AI coding assistant does more than answer one-off prompts. It can inspect a project directory, reason over multiple files, propose test scaffolding, and work in a continuous loop with the engineer — rather than waiting to be prompted at each step. The practical bottleneck for… Continue reading Free and Paid Ways to Run Cloud Code for Agentic Testing and QA