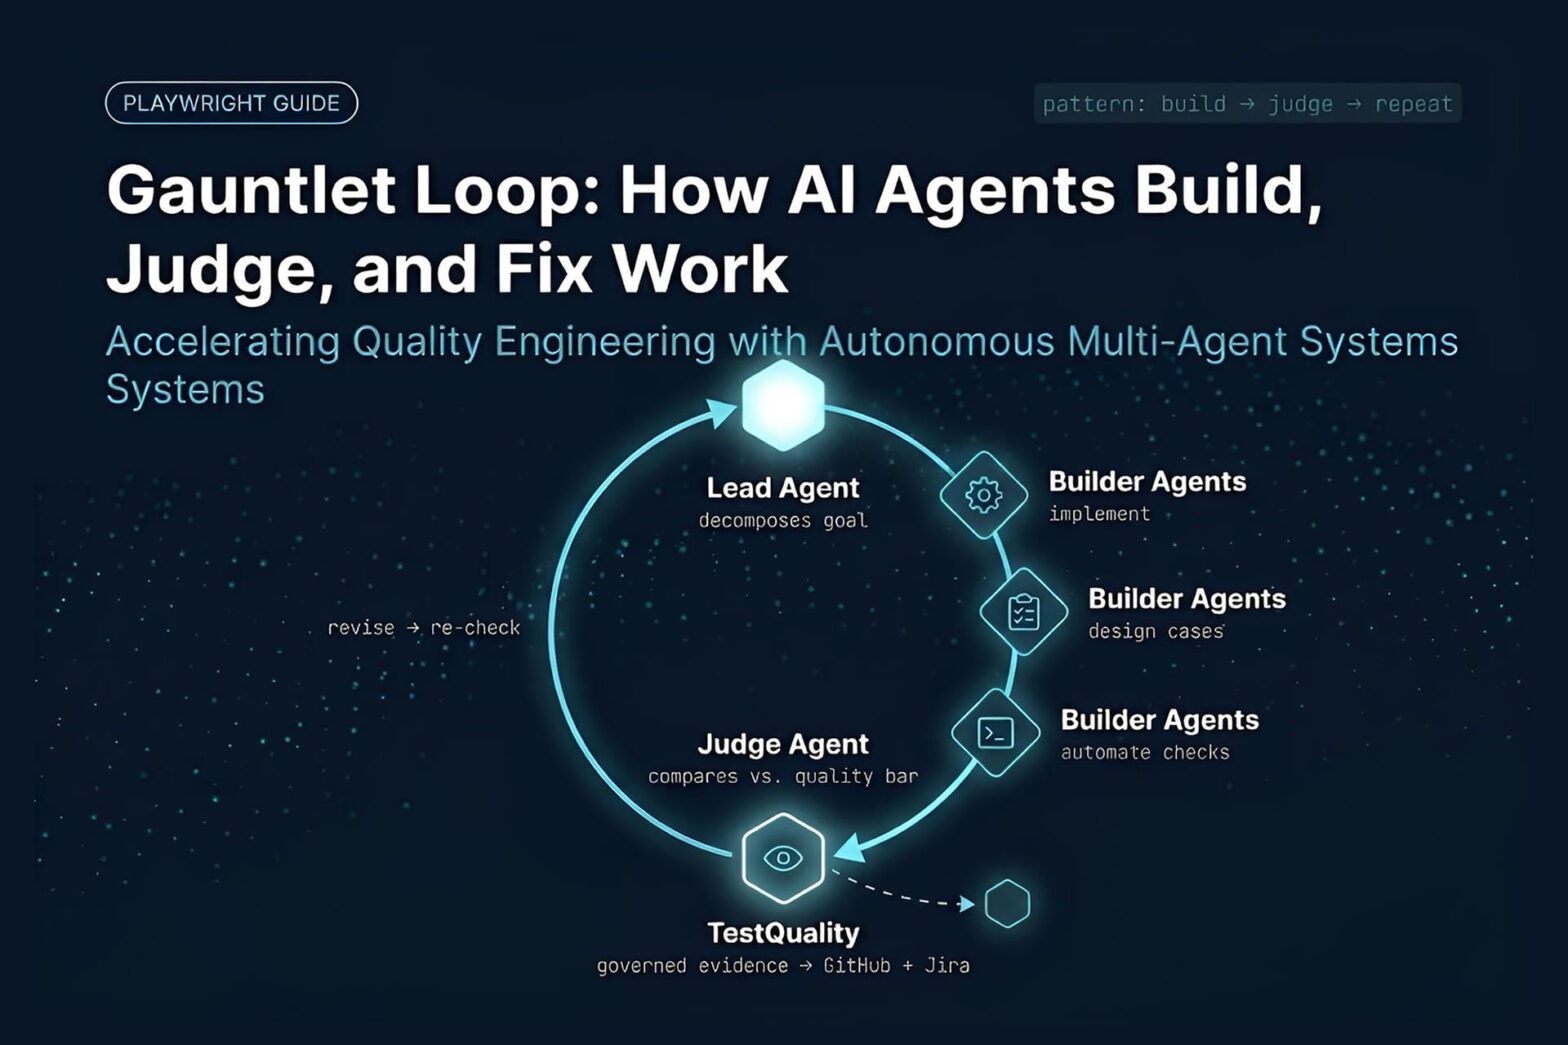
A Gauntlet Loop is an agentic AI workflow in which a lead agent breaks a broad goal into small, independently judgeable pieces, assigns them to specialist builder agents, and routes every result through a separate judge agent that compares the work against a quality bar. The pattern was popularized by Matt Shumer’s July 2026 “Claude… Continue reading Gauntlet Loop: How AI Agents Build, Judge, and Fix Work
Tag: Playwright
Building an Agentic Playwright Framework for QA Teams
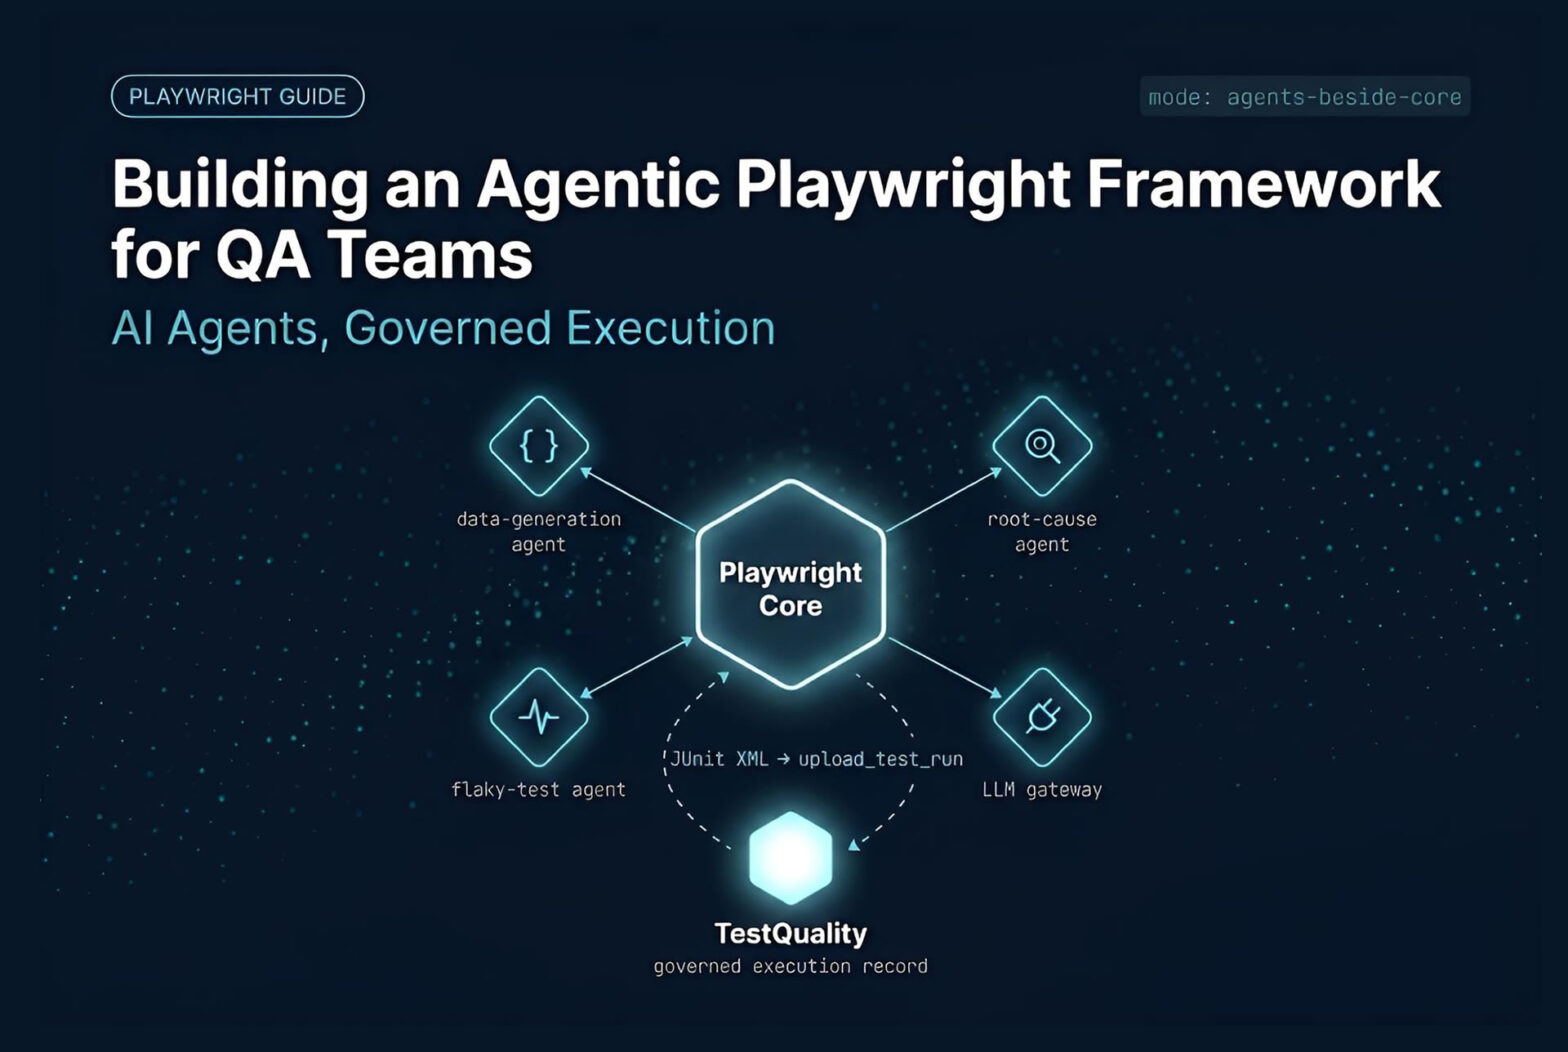
An agentic Playwright framework is a Playwright test suite extended with AI agents that handle bounded work around execution: generating schema-controlled test data, analyzing failure evidence, and surfacing flaky-test patterns. Playwright still owns browser automation, assertions, and pass/fail reporting — agents sit beside that loop, not inside it. Each agent reads a defined input, such… Continue reading Building an Agentic Playwright Framework for QA Teams
How To Integrate Agentic Testing Into Your CI/CD Pipeline
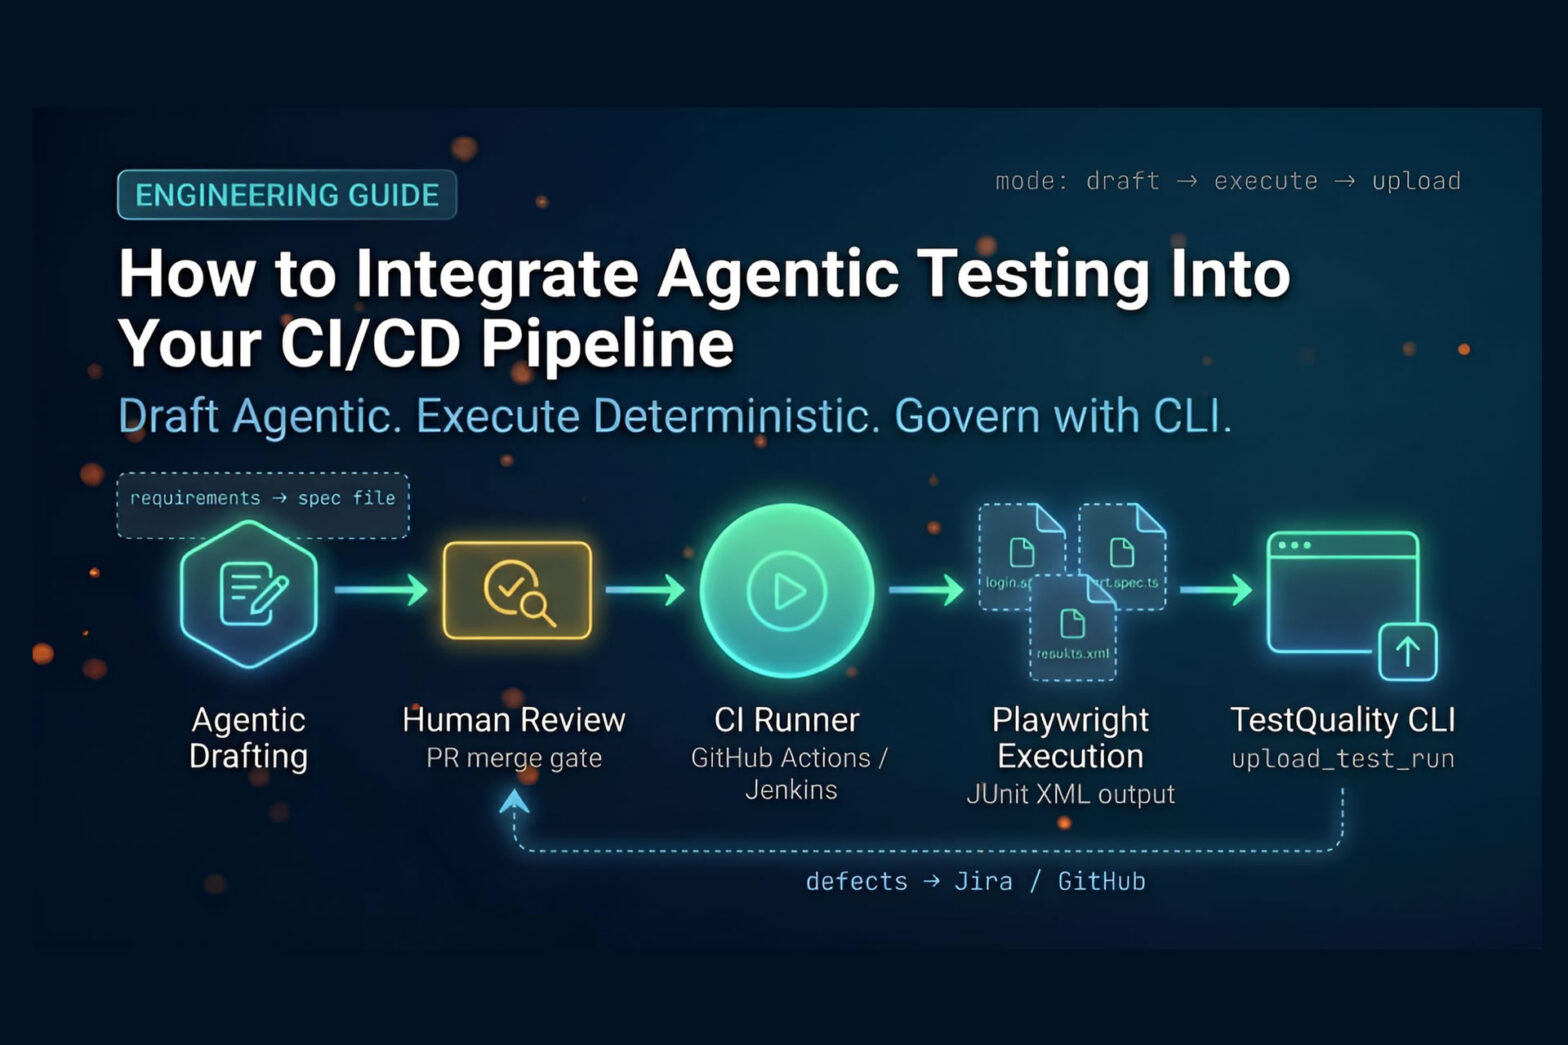
At a Glance Agentic Testing in CI/CD: Where the Boundary Is and How to Cross It Cleanly AI drafts the tests. Playwright runs them. The CLI governs both. The boundary is strict: Agentic tools belong in the drafting layer — analysis, coverage planning, and script generation. Deterministic frameworks like Playwright or Selenium own execution. Mixing… Continue reading How To Integrate Agentic Testing Into Your CI/CD Pipeline