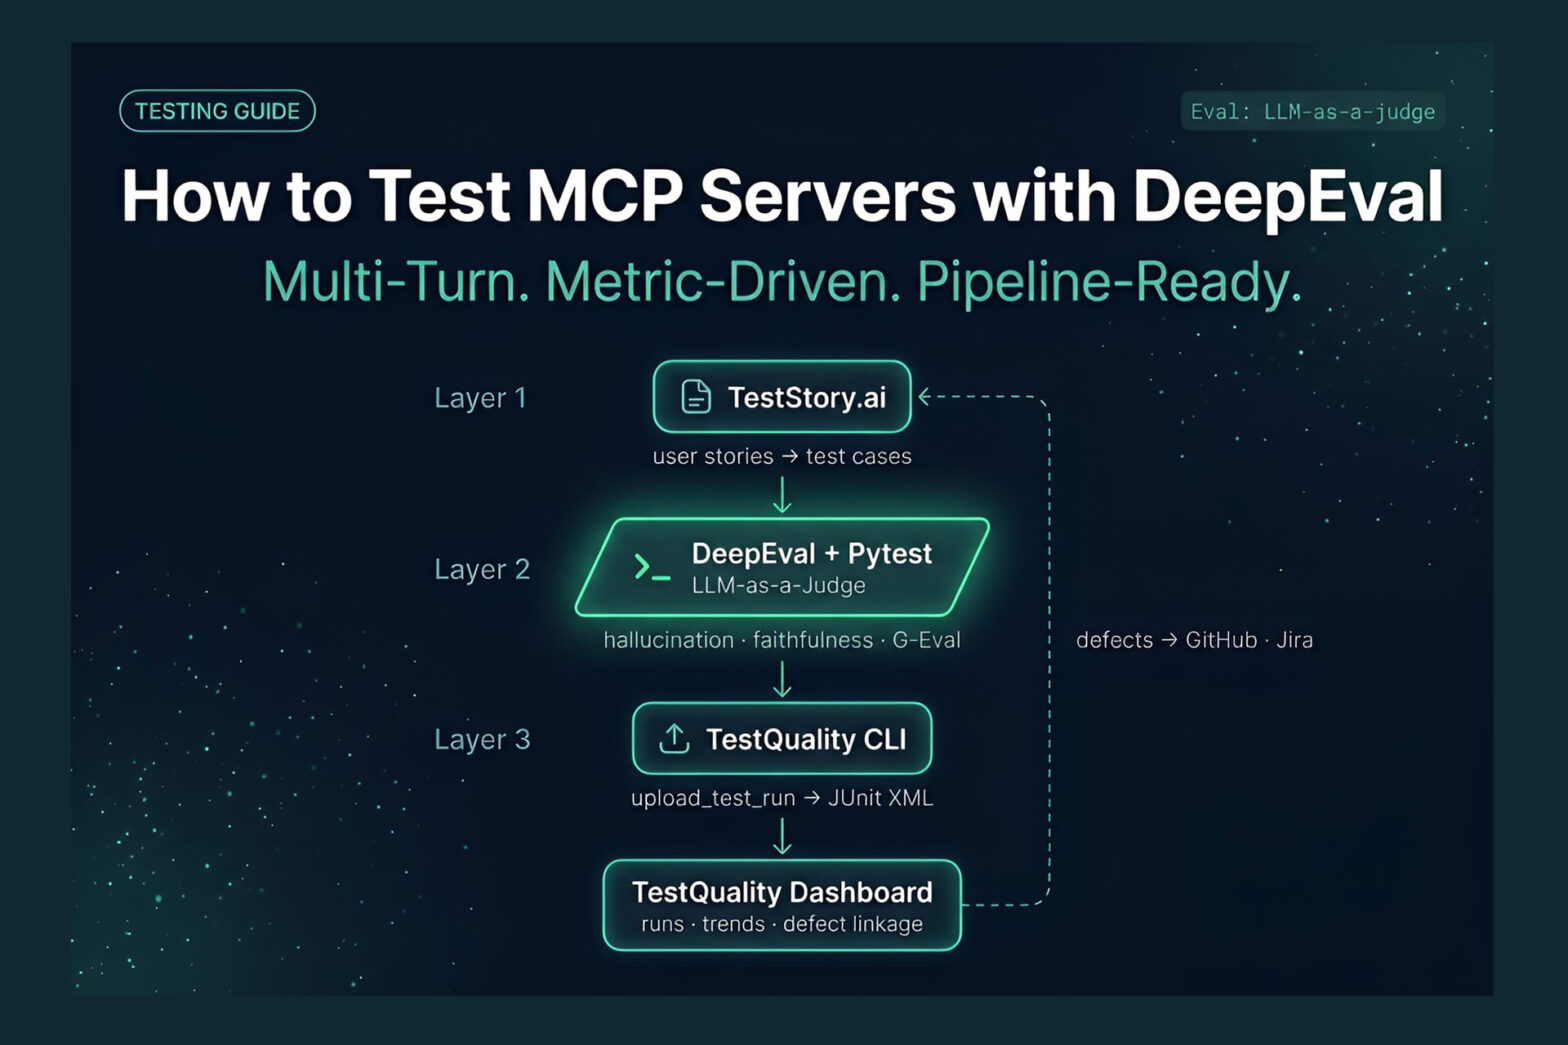
MCP server testing is the practice of validating that a Model Context Protocol server exposes the right tools, passes the right context, preserves session state across turns, and returns outputs an LLM can use correctly in real agentic workflows. For QA teams building AI products, this means testing not just API responses but complete tool-driven… Continue reading How to Test MCP Servers with DeepEval
Tag: LLM Evaluation
How to Test AI Agents: A Step-by-Step Evaluation Guide
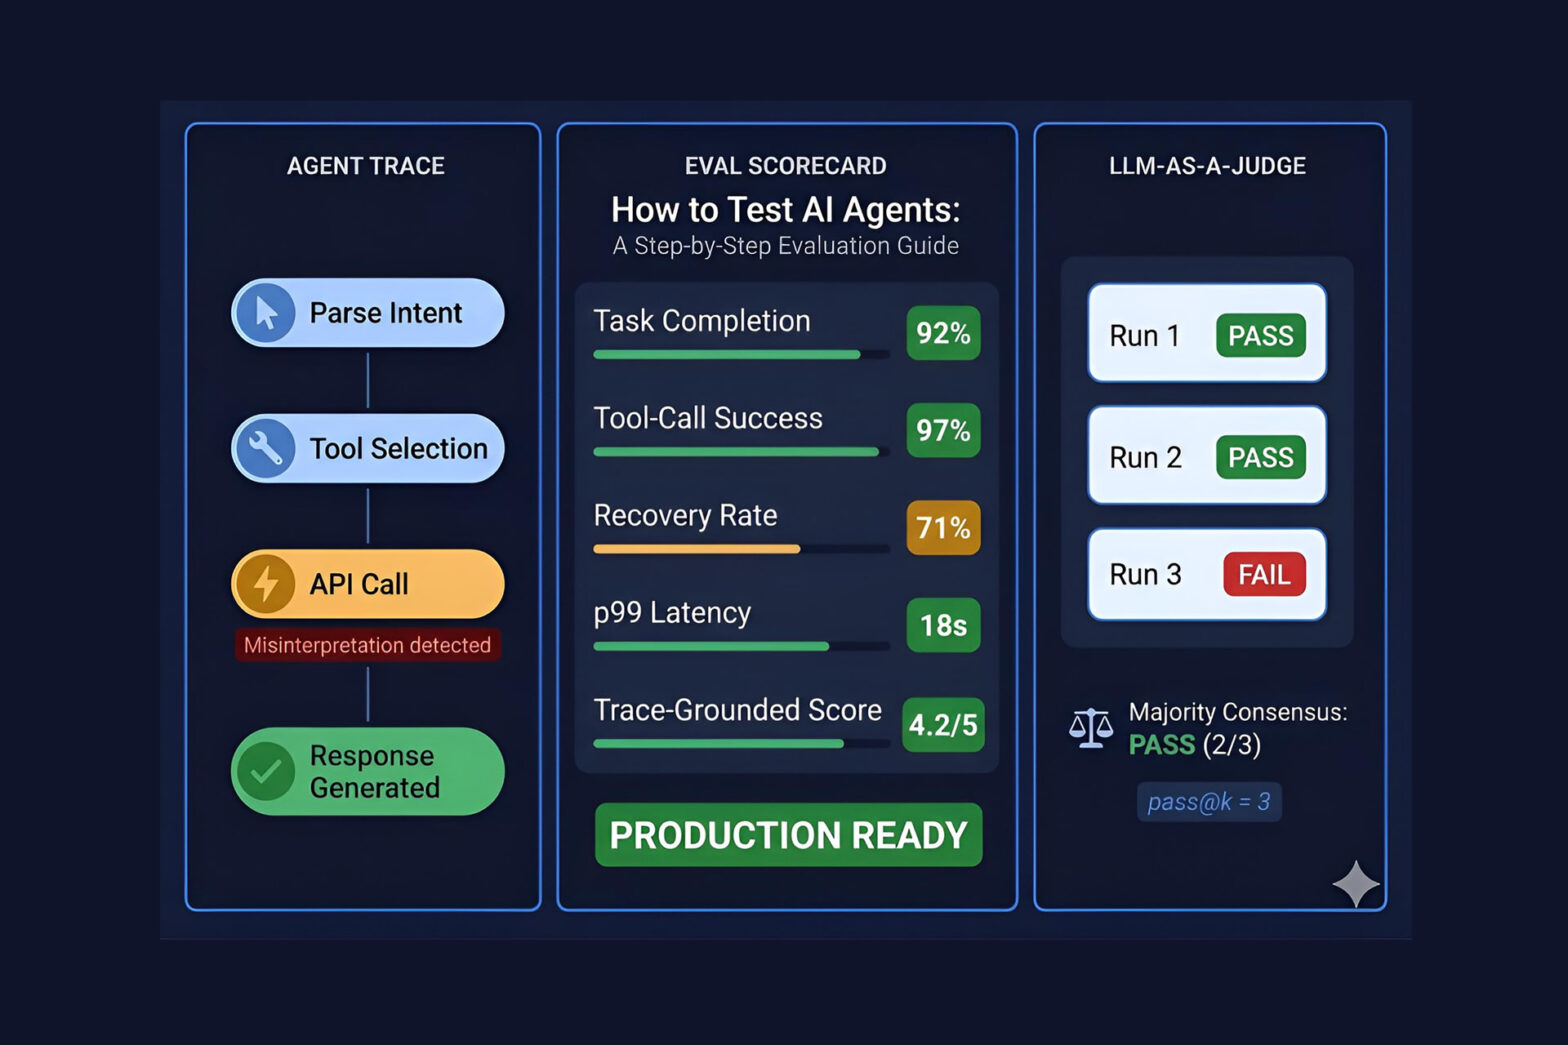
At a Glance How to Test AI Agents: What Every QA Team Needs to Know A correct final answer does not mean a correct agent — trajectory matters as much as outcome. Dual-layer evaluation: Testing AI agents requires validating both the orchestration layer (tool selection, argument construction) and the reasoning layer (context interpretation, decision quality)… Continue reading How to Test AI Agents: A Step-by-Step Evaluation Guide
Beyond the Basics: Advanced LLM Evaluation Metrics and Strategies for QA Success
The integration of Large Language Models (LLMs) into applications is rapidly transforming the software landscape. As we discussed in our Guide to LLM Testing and Evaluation previous post, while LLMs offer unprecedented capabilities, their non-deterministic nature presents unique and evolving challenges for quality assurance. As QA professionals and developers, we’ve moved past the initial awe… Continue reading Beyond the Basics: Advanced LLM Evaluation Metrics and Strategies for QA Success
A Guide to LLM Testing and Evaluation for Modern QA Teams
Introduction The world of software is undergoing a seismic shift. Large Language Models (LLMs) are no longer a novelty; they are being integrated into a vast array of applications, from customer support chatbots to sophisticated code generation tools. For QA professionals and developers, this represents a new frontier in software testing as well, one that… Continue reading A Guide to LLM Testing and Evaluation for Modern QA Teams