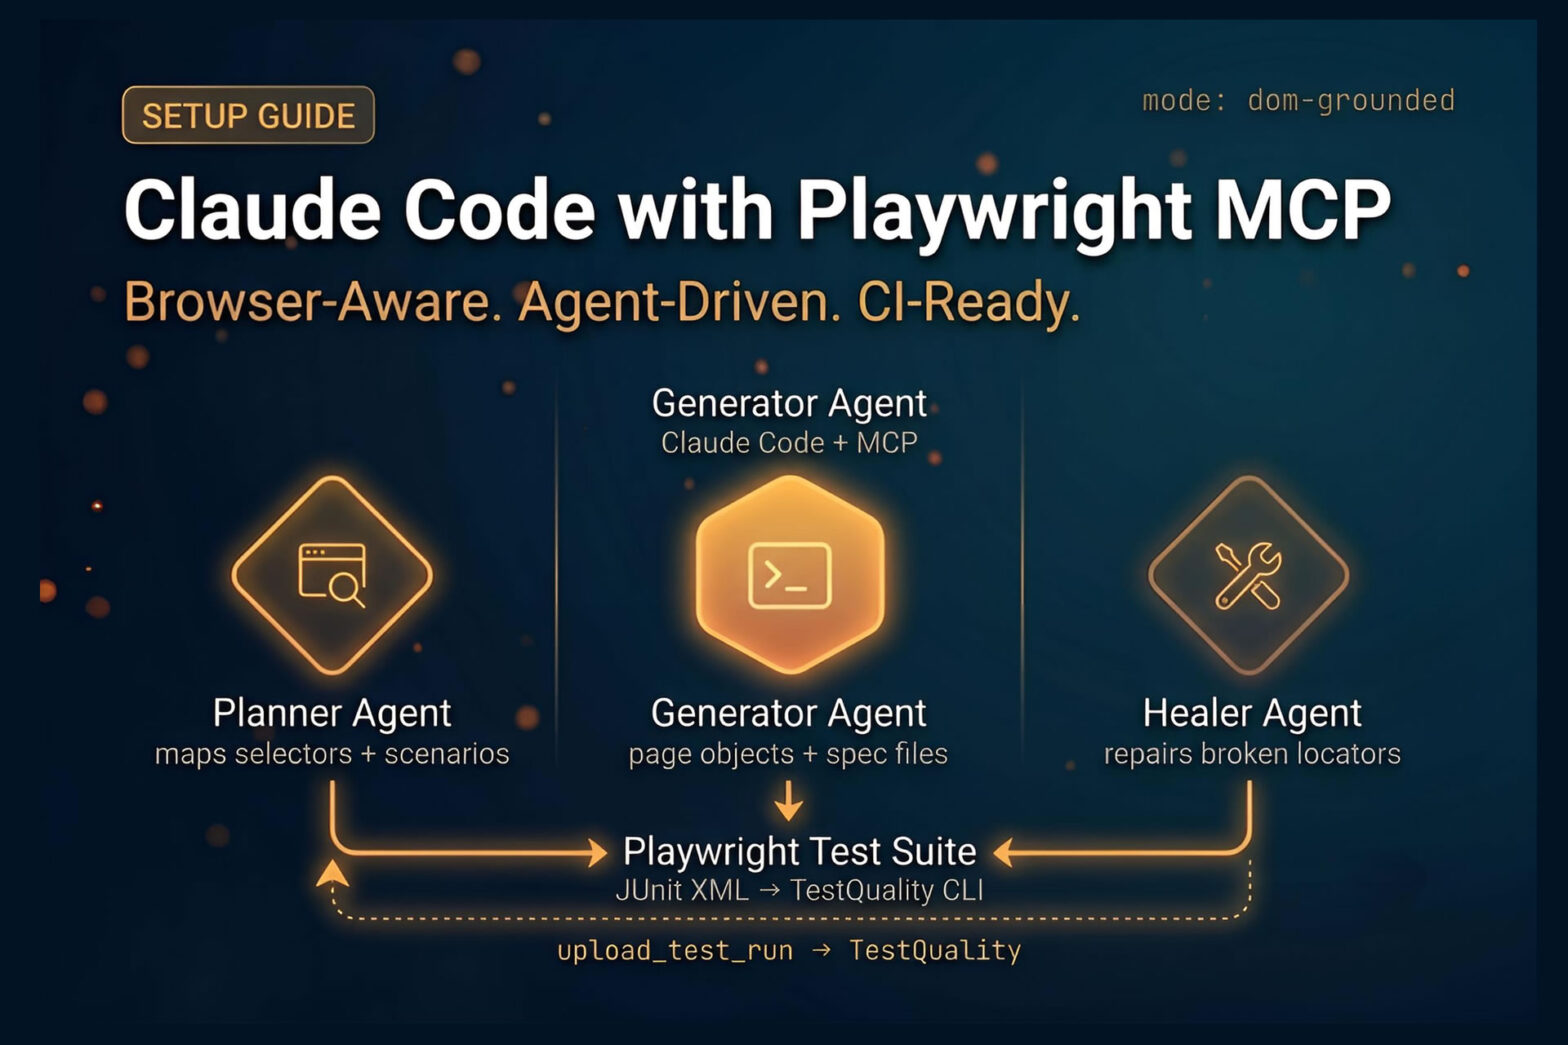
Claude Code with Playwright MCP is an agentic QA workflow where Claude Code uses the Playwright Model Context Protocol server to connect a coding agent to a live browser. The agent navigates the application, reads the actual DOM, captures real selectors, and generates executable Playwright tests from what it observes — instead of guessing page… Continue reading Claude Code with Playwright MCP: Agentic AI Test Automation Setup Guide
Category: Agentic QA
Agentic QA is the next evolution of software testing — where autonomous AI agents read user stories and requirements, generate test cases across manual, exploratory, BDD, and automated testing workflows, self-heal broken selectors, and maintain full coverage without human intervention at every step. This category covers the architecture, tooling, and real-world implementation of Agentic QA — from Plan-Act-Verify reasoning loops and LLM-based visual regression to intelligent test prioritization, HITL validation, and native CI/CD pipeline integration. Whether your team runs Gherkin scenarios, Playwright suites, unit tests, or structured manual cycles, this is where autonomous AI changes how testing gets done.
Explore how TestStory.ai Agent and TestQuality power the shift from reactive test authoring to outcome-driven quality engineering.
How To Integrate Agentic Testing Into Your CI/CD Pipeline
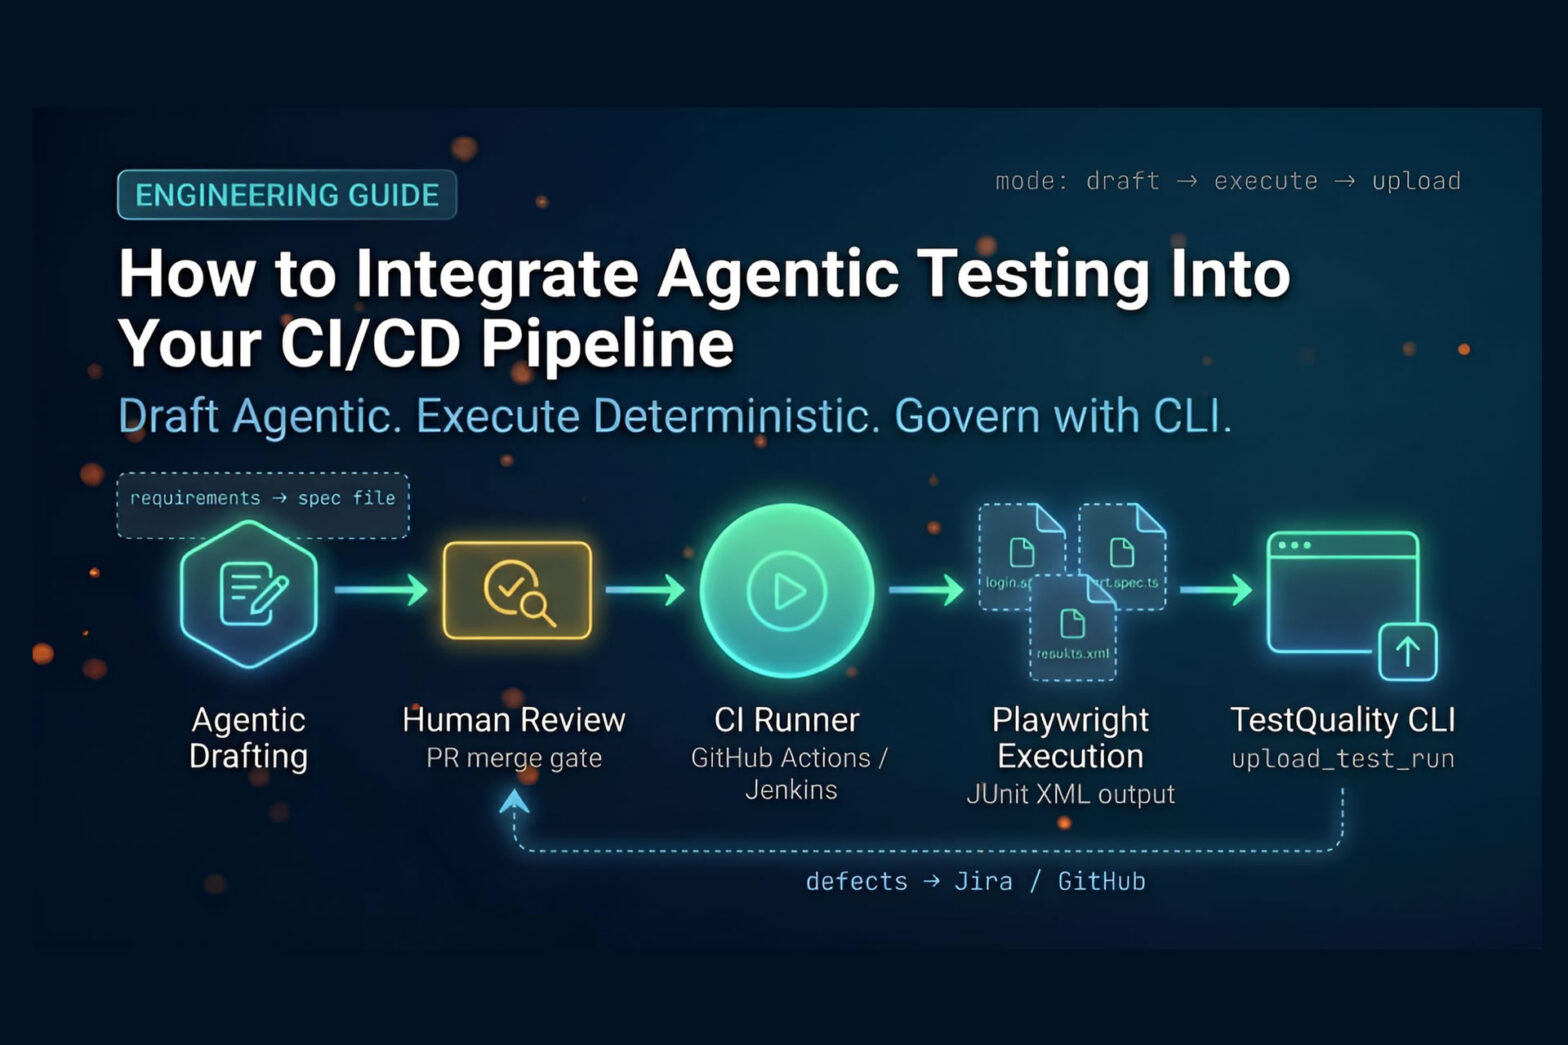
At a Glance Agentic Testing in CI/CD: Where the Boundary Is and How to Cross It Cleanly AI drafts the tests. Playwright runs them. The CLI governs both. The boundary is strict: Agentic tools belong in the drafting layer — analysis, coverage planning, and script generation. Deterministic frameworks like Playwright or Selenium own execution. Mixing… Continue reading How To Integrate Agentic Testing Into Your CI/CD Pipeline
Agentic Testing and How QA Teams Can Use Claude Code and Terminal Agents
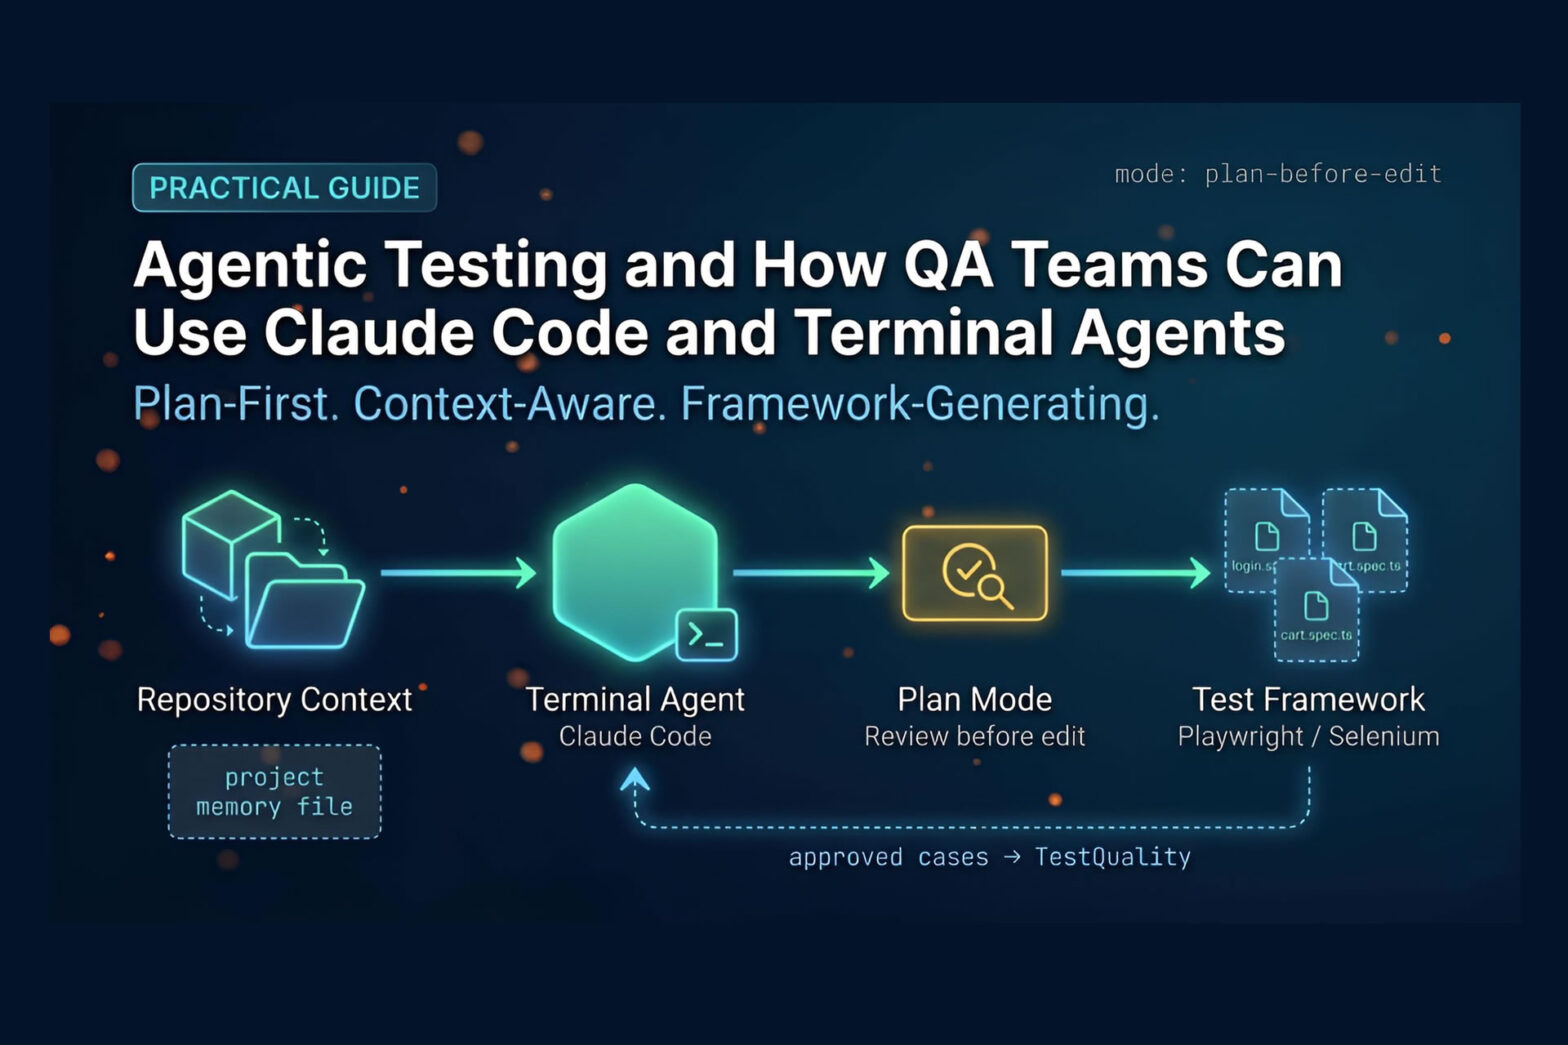
Agentic Testing and QA is a practice in which AI agents operate directly on a project — reading files, planning tasks, generating framework code, and interacting with a browser — rather than simply answering prompts inside a chat window. Tools like Claude Code bring this capability to the terminal, giving QA teams a command-line assistant… Continue reading Agentic Testing and How QA Teams Can Use Claude Code and Terminal Agents
Free and Paid Ways to Run Cloud Code for Agentic Testing and QA
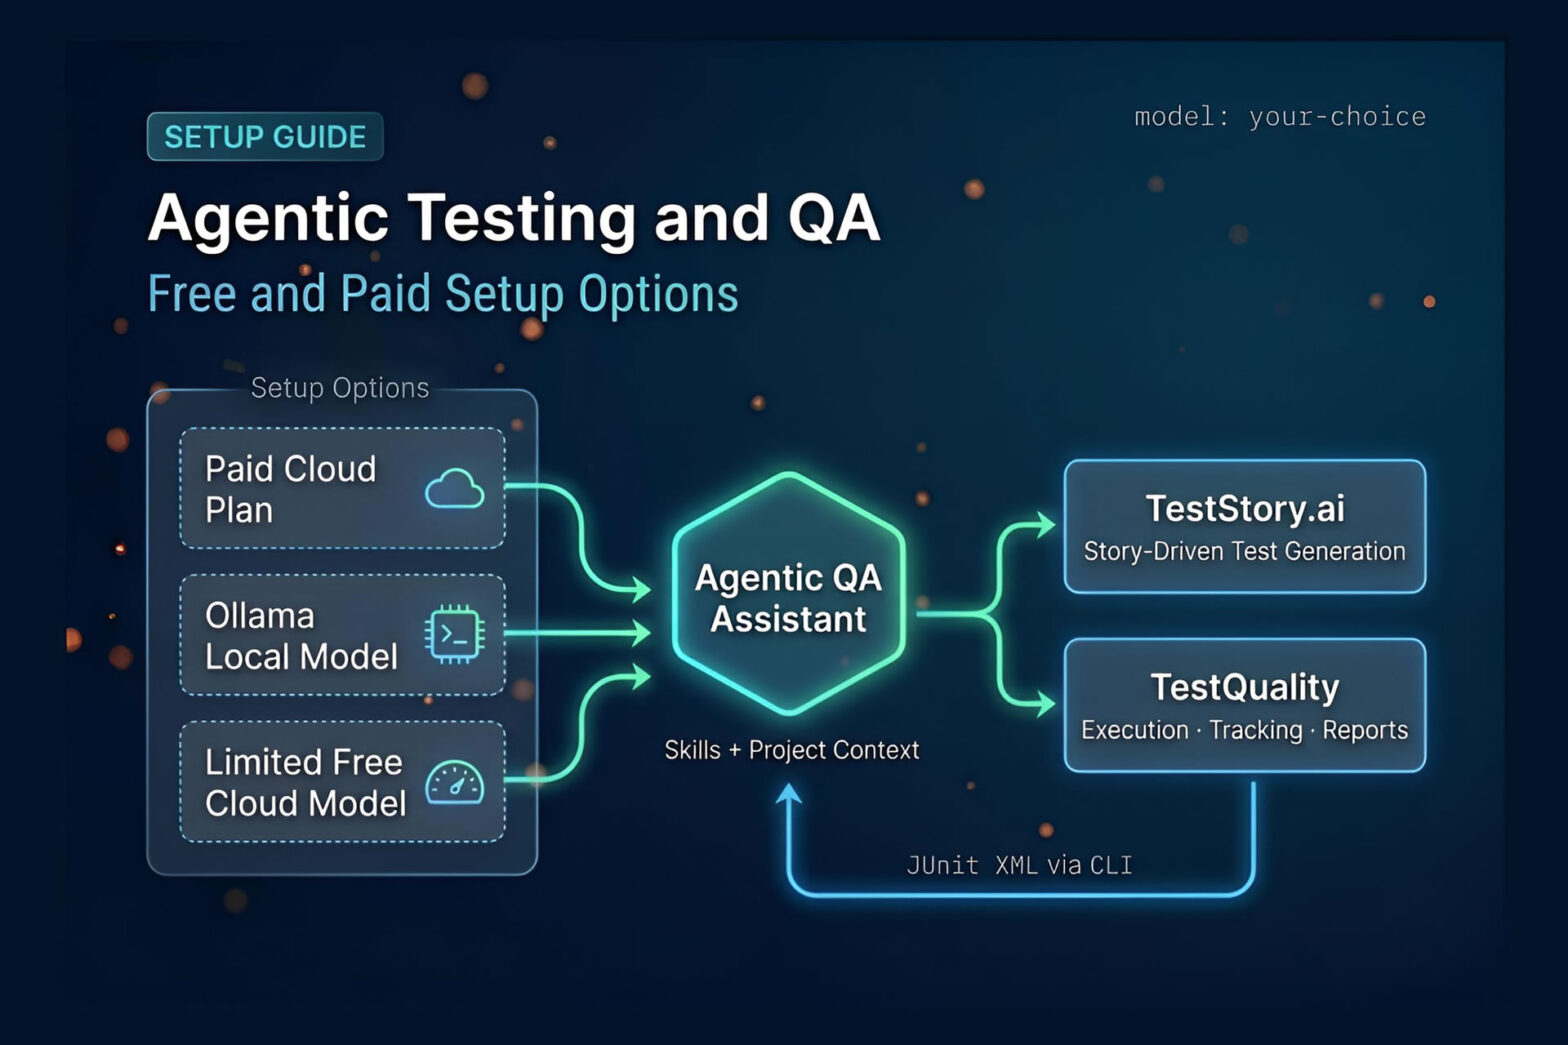
Agentic Testing and QA describes a testing workflow where an AI coding assistant does more than answer one-off prompts. It can inspect a project directory, reason over multiple files, propose test scaffolding, and work in a continuous loop with the engineer — rather than waiting to be prompted at each step. The practical bottleneck for… Continue reading Free and Paid Ways to Run Cloud Code for Agentic Testing and QA
How Does AI-Driven Test Creation Reduce QA Workload?
AI-driven test creation cuts the most time-consuming parts of QA, freeing engineers to focus on strategy, exploration, and edge cases instead of typing the same scenarios over and over. If your QA team is drowning in test backlog, AI-driven test creation is the difference between shipping on time and shipping late. QA teams are buried.… Continue reading How Does AI-Driven Test Creation Reduce QA Workload?
Agentic Testing and QA: An AI Framework for Chatbots & RAG
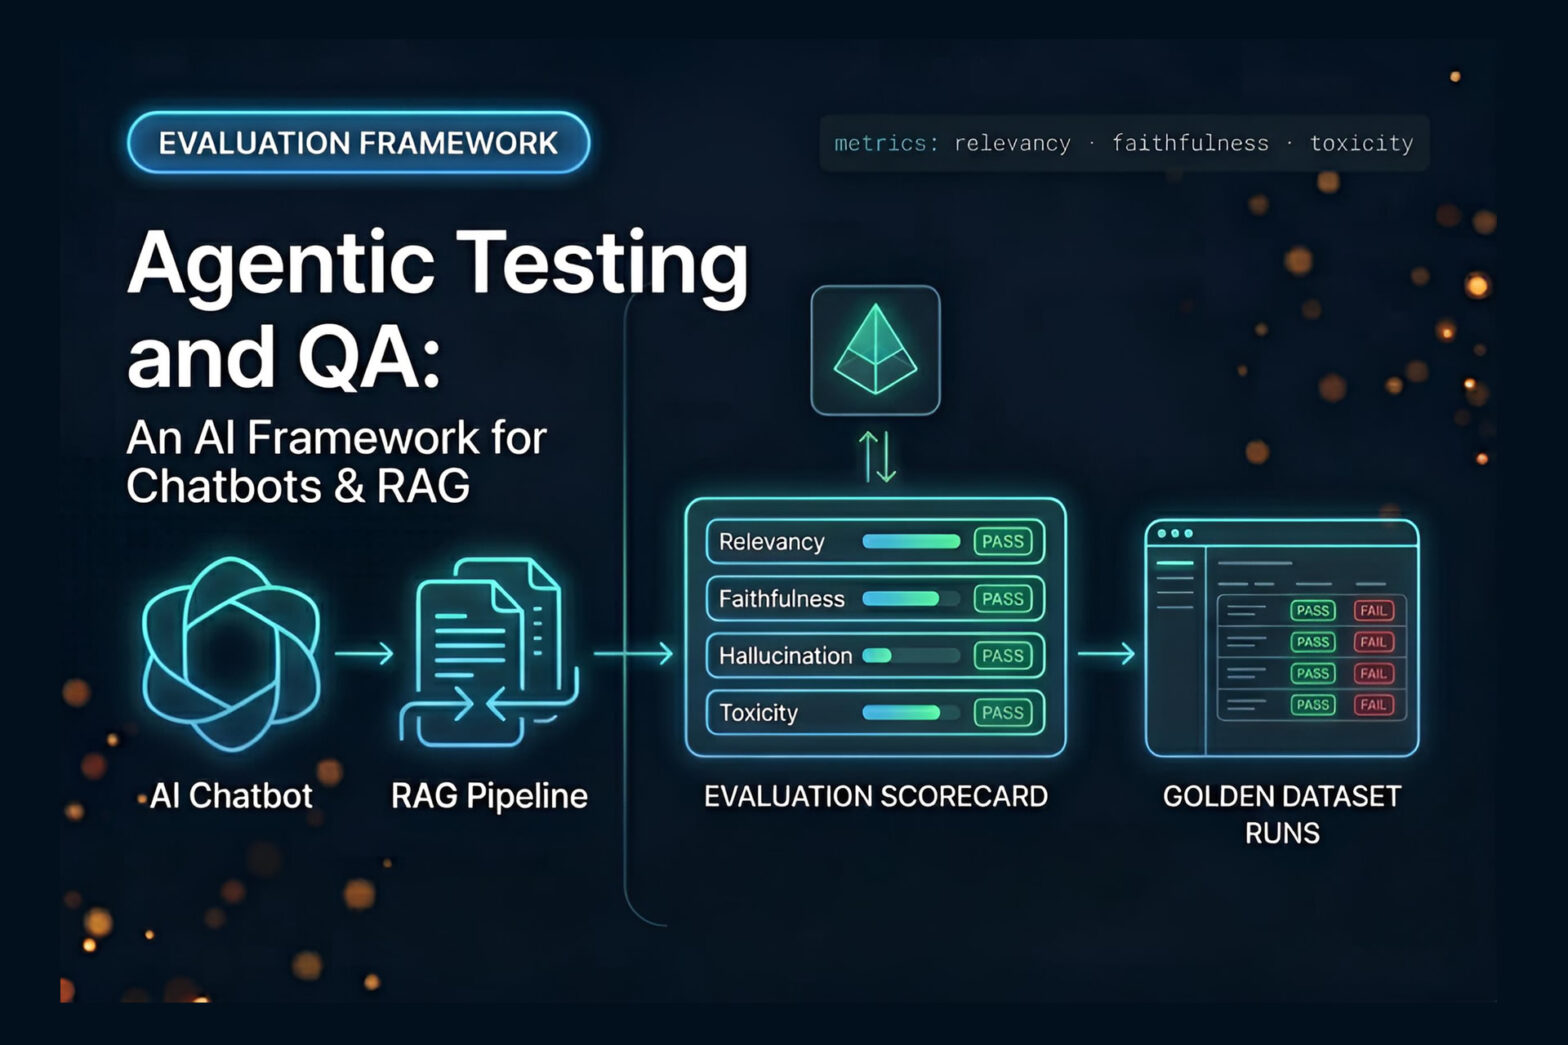
At a Glance Why Traditional Automation Fails AI Systems — and What to Do Instead Pass/fail is not enough when your system can hallucinate, drift, or refuse incorrectly. The core shift: AI systems require evaluation across multiple quality dimensions — relevance, faithfulness, hallucination risk, toxicity, and retrieval grounding — not a single pass/fail assertion. Golden… Continue reading Agentic Testing and QA: An AI Framework for Chatbots & RAG
Best Test Management Tools 2026: AI Features Compared
At a Glance 9 tools, 5 criteria, 1 buying decision Independent comparison for QA leads evaluating test management software in 2026. Pricing transparency is now a differentiator: only 7 of 9 leading tools disclose pricing publicly — Tricentis qTest and Jira Rovo gate costs behind sales conversations. Jira integration falls into 3 patterns: native marketplace… Continue reading Best Test Management Tools 2026: AI Features Compared
Playwright Test Agents & MCP: A 2026 Architecture Guide
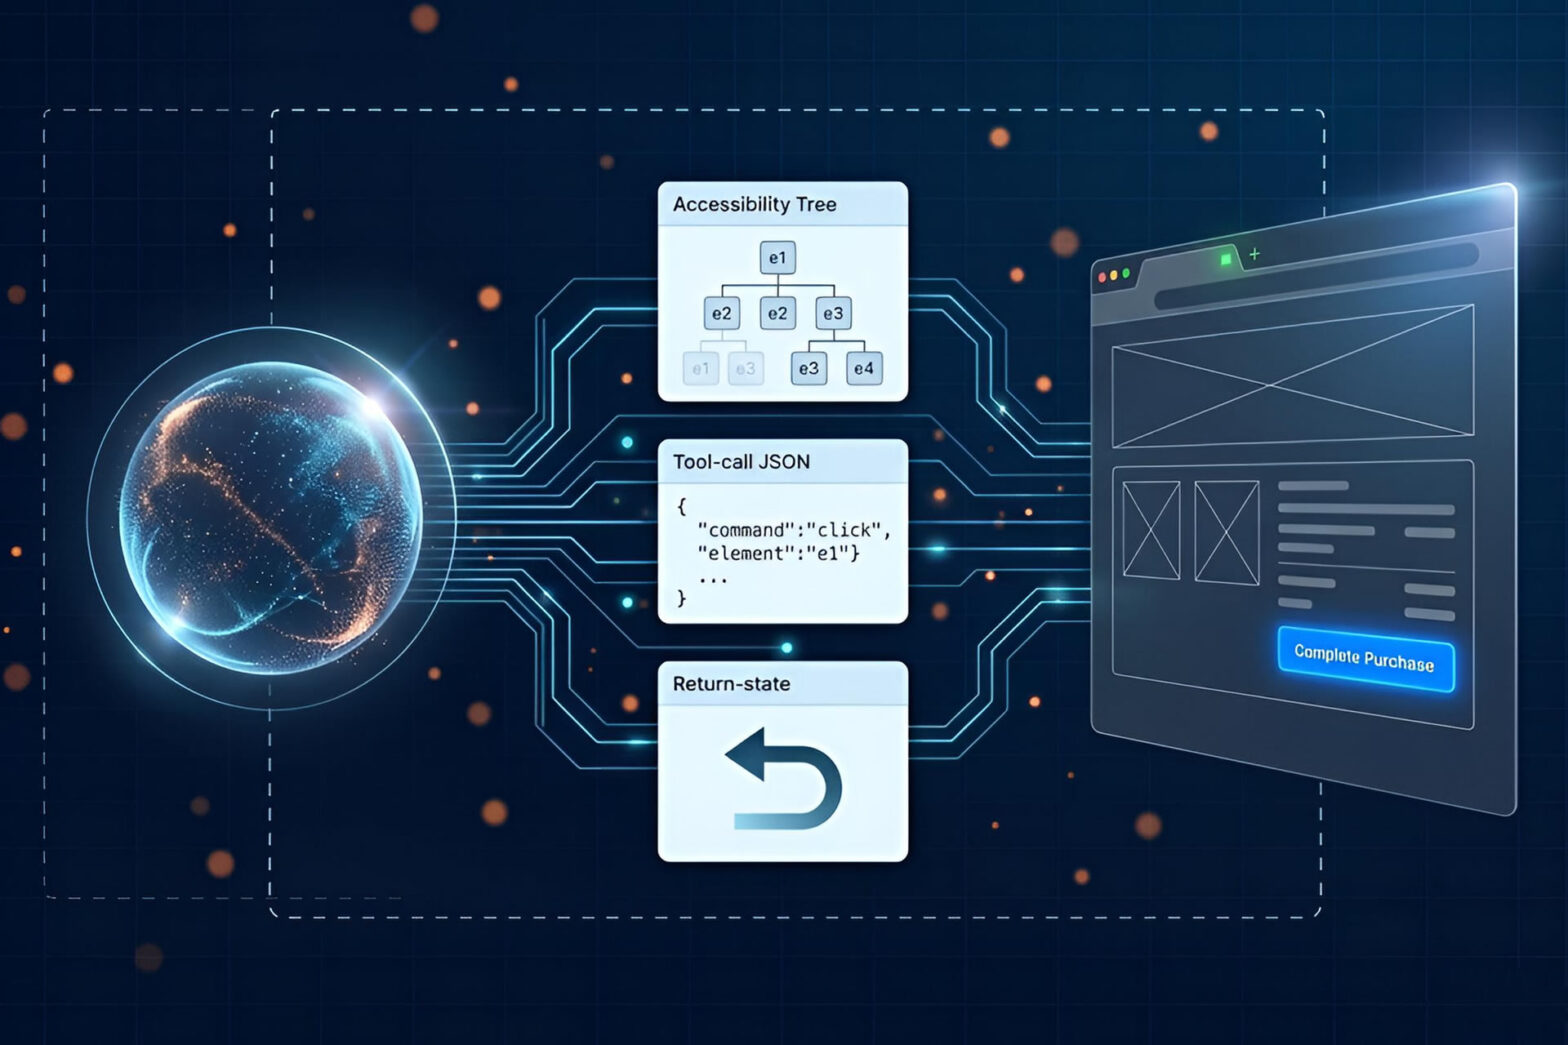
At a Glance Playwright Test Agents and MCP — A 2026 Architecture Decision Strategic guidance for engineering leaders evaluating agentic Playwright workflows Definition: Playwright test agents are LLM-driven execution loops that interpret high-level intent via the Model Context Protocol (MCP), rather than executing hardcoded selectors. Token economics: Microsoft’s MCP server consumes ~200–400 tokens per accessibility-tree… Continue reading Playwright Test Agents & MCP: A 2026 Architecture Guide
Playwright Flaky Tests: The 2026 Fix Playbook
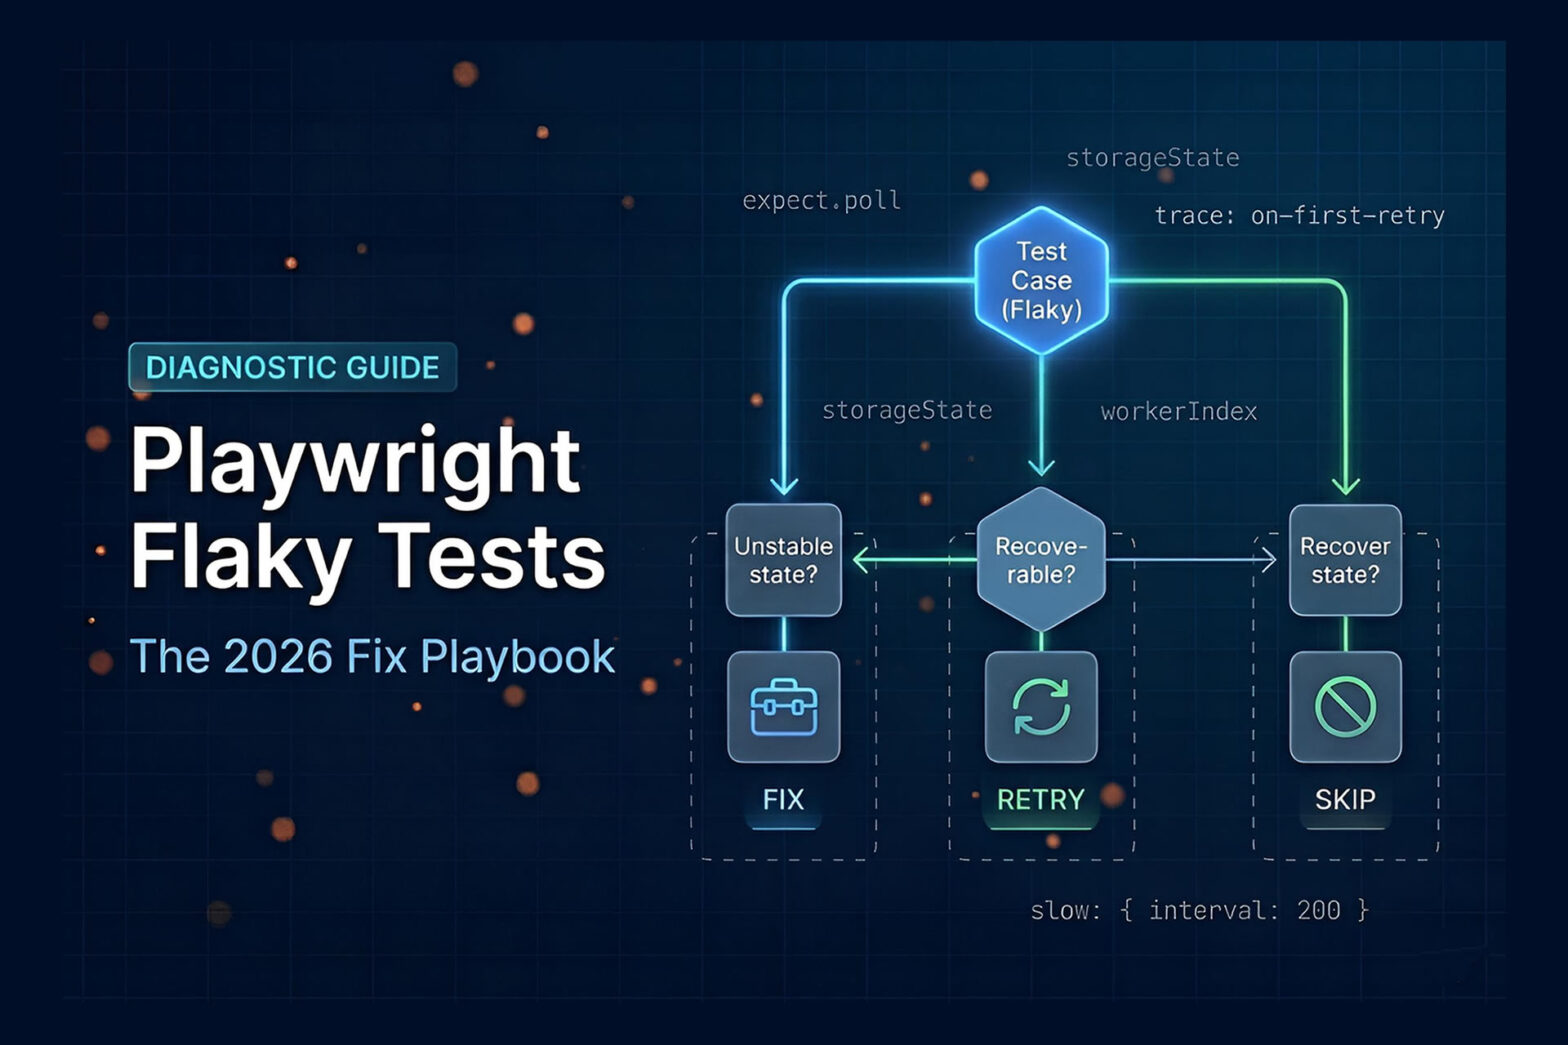
At a Glance Five diagnostic patterns. One decision tree. A senior practitioner’s triage playbook for Playwright flakiness in 2026. Flakiness is architectural, not framework-borne: Almost every flake traces back to async state, locator drift, session pollution, environment variance, or AI-agent non-determinism — not to Playwright itself. The fix is bigger than the diagnosis: Replace static… Continue reading Playwright Flaky Tests: The 2026 Fix Playbook
Beyond RAG: How Agentic Memory Solves Context Rot in AI Agents
Key Takeaways Agentic Memory: The Persistence Layer Beyond RAG Stop rebuilding context every session. Start writing it once and remembering it forever. Silent Semantic Errors Dominate Multi-Agent Failures: Eliminate the silent semantic drift behind 75.17% of multi-agent failures by anchoring agents to persistent state. A-MEM Doubles Multi-Hop Reasoning Performance:Research from Xu et al. at NeurIPS… Continue reading Beyond RAG: How Agentic Memory Solves Context Rot in AI Agents